

Introduction
Crawl budget optimisation helps search engines spend their crawling activity on URLs that matter. It is most relevant to large websites, frequently updated sites, and sites where evidence shows that Googlebot repeatedly requests low-value URLs or struggles to discover important pages. Duplicate URL patterns, orphan pages and redirect chains can all make crawling less efficient, but they do not automatically cause ranking losses or indexing delays. The first step is to establish what is happening, then apply a fix that suits the URL’s purpose and check the outcome.
Table of Contents
When Crawl Budget Optimisation Is Necessary
Understanding Crawl Capacity and Crawl Demand
Google describes crawl budget through two related factors: crawl capacity and crawl demand. Capacity reflects how much crawling a server can handle without being overloaded. Demand depends on site size, update frequency, popularity and the perceived value of URLs. If a server slows down or returns repeated errors, Google may reduce crawling. More server capacity alone will not lead to more crawling if demand is low. See Google’s crawl-budget guidance for its current explanation.
Recognising Signs of a Crawl-Efficiency Problem
A closer audit may be worthwhile when a large site generates many URL variations, product or listing pages change frequently, or server logs show repeated Googlebot requests to low-value URLs. Another signal is a sizable group of important pages reported as discovered but not indexed, although that status alone does not prove a crawl-budget issue. Start with Google Search Console, a site crawl and, where available, server logs. Look for a pattern that affects useful URLs rather than treating one unusual report as a diagnosis.
Separating Crawling, Indexing and Ranking
Crawling means a search engine requests a URL. Indexing is the separate process of assessing and potentially storing the page for search. Ranking determines where an eligible page appears for a query. A page can be crawled without being indexed, and an indexed page may not rank prominently. Duplicate content, weak internal linking or quality issues can affect the later stages even when crawling works normally. Diagnose each stage separately before changing directives or redirect rules.
Diagnose Duplicate and Parameterised URLs
Identifying Common Sources of Duplicate URL Patterns
Duplicate or near-duplicate URLs often come from tracking parameters, sorting options, product filters, session IDs, or alternate versions of a URL. For example, /shoes/, /shoes/?colour=black and /shoes/?colour=black&sort=price may lead to pages with substantial overlap. Not every variation is harmful: a filter page might meet a distinct search need. The task is to identify which URLs provide useful, distinct content and which exist only because of site functionality. Do not assume that every parameter should be removed or blocked.
Grouping URL Variants with a Website Crawl
Use a crawler to export URL addresses, status codes, canonical tags, indexability and incoming internal links. Group results by recurring patterns, such as query parameters, uppercase and lowercase paths, trailing slashes or HTTP and HTTPS versions. Compare a sample of URLs within each group to confirm whether the content is duplicated or meaningfully different. Check that internal links, XML sitemaps and canonical tags consistently point towards the preferred version. A spreadsheet can help prioritise patterns by the number of URLs involved, their purpose and whether they receive internal links or Googlebot requests.
Managing Faceted Navigation Without Blocking Valuable Pages
Faceted navigation lets shoppers refine products by criteria such as size, colour, brand or price. Some combinations can be useful landing pages; many others may generate almost identical results. A UK retailer selling work boots might want a clear category page for a popular type of boot, but not thousands of combinations created by every possible size, colour and sorting choice. Decide which filtered pages deserve to be discoverable and indexable, then keep internal links and canonical signals consistent. Avoid relying on nofollow as a dependable crawl-budget control. For detailed filter strategy, link to Midland’s faceted navigation SEO guide.
Find and Evaluate Orphan Pages
Comparing Website Crawls with XML Sitemaps and CMS Data
An orphan page has no incoming internal links within the website and crawl scope being assessed. To find candidates, crawl the site from its internal links and export URLs from the XML sitemap. Compare those lists with URLs in the content management system or database, if available. A URL found in a sitemap but not in the crawl may be orphaned, or the crawler may have missed it because of its settings or discovery limits. Check before classifying it. Sitemaps identify candidates; they do not show the full internal-link structure.
Cross-Checking Search Console, Analytics and Server Logs
Use Search Console to review indexing reasons and inspect individual URLs. Analytics landing-page data can highlight pages that still receive visits, while server logs show requests recorded by the server, including verified Googlebot. These sources answer different questions: analytics shows visits, logs show server requests, and Search Console reports Google’s view of crawling and indexing. Combine them with crawl and sitemap exports to investigate URLs that appear in one source but lack internal links in another.
Classifying Orphan URLs Before Making Changes
Do not automatically delete every orphan URL. Check whether it has value, receives visits or links, or serves a user’s needs. If useful, add links from a relevant category or related page. If it duplicates a stronger page, consider consolidation and a relevant redirect. If it has been permanently removed with no suitable replacement, return a 404 or 410 response. A valid page can remain live even when it is not part of the main navigation.
Diagnose and Fix Redirect Chains
Mapping the Full Redirect Path and Final Response
A redirect chain occurs when one URL sends a request to another URL that redirects again before reaching the destination. For example: A → 301 → B → 301 → C → 200 OK. Use a crawler or redirect-checking tool to record each hop, response code and final URL. Confirm that the destination loads successfully and contains the content users expect. A single redirect is not automatically a serious SEO issue, but Google recommends avoiding long chains because they can make crawling less efficient.
Updating Redirect Rules and Internal Links
Where the destination is correct, update the redirect configuration so the original URL points directly to the final destination when appropriate. Then update internal links so menus, body copy, breadcrumbs and other site elements link to the final URL instead of an intermediate redirect. Check XML sitemaps too; they should list the preferred, canonical URLs rather than addresses that redirect. During a site migration, preserve the intended mapping between old and new pages. Do not redirect unrelated old URLs to a generic page simply to avoid errors; the destination should be a genuine replacement where one exists.
Validating Redirects, Loops and Destination Relevance
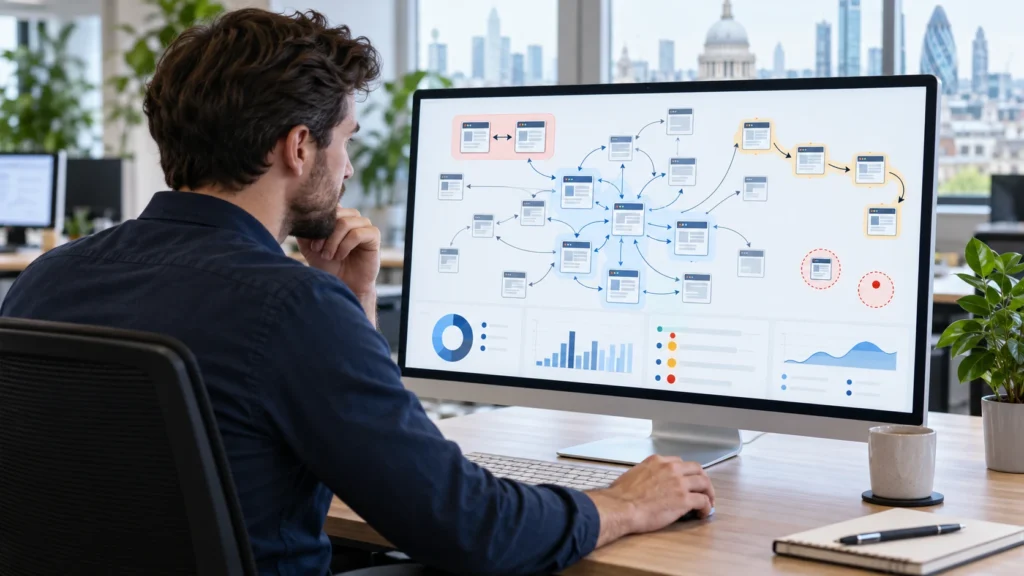
Re-crawl the affected URLs after implementation. Confirm that each redirect reaches the expected destination, that the final response is appropriate, and that no loop or redirect to an irrelevant page has been introduced. Check both the original URLs and internal links that previously pointed to them. Keep a record of the before-and-after paths, especially after migrations or bulk rule changes. Fixing a chain improves the route to the destination, but it does not guarantee that the destination will be indexed or rank better; those outcomes depend on other signals as well.
Choose the Correct Fix for Each URL Problem
Using Redirects and Canonical Tags for Duplicate URLs
Use a permanent redirect when an old URL should no longer act as a separate page and a relevant replacement exists. Use a canonical tag when duplicate or similar versions must remain accessible, but you want to indicate the preferred URL. Canonical tags are signals, not instructions, so reinforce them with consistent internal links and sitemap entries. Google’s canonicalisation guidance explains the signals it considers. First decide whether the URLs should remain separate, be consolidated, or have a preferred version selected.
Applying Noindex and Robots.txt Correctly
Noindex tells search engines not to include a page in search results when they can crawl and process the directive. A robots.txt rule controls whether a crawler can request a URL; it does not guarantee removal from search results. If robots.txt blocks a page, Google may not see its noindex tag. Use noindex when a page must remain accessible but should not appear in search. Consider robots.txt for defined URL patterns only after checking the implications. Google’s noindex documentation explains the access requirement.
Handling Removed Pages and Unwanted URL Variants
Choose the response according to the page’s purpose. Redirect to a relevant replacement if content has moved; return 404 or 410 if it has been removed with no suitable replacement. Improve internal links when important pages are hard to discover. Assess parameterised URLs before restricting crawling, as some filtered pages are useful to searchers. Robots.txt, canonical tags, noindex and redirects solve different problems: consolidation, crawl control, search exclusion and removal are not interchangeable.
Situation | Action to consider |
A URL has a suitable replacement | Use a relevant permanent redirect |
Duplicate versions must remain accessible | Use consistent canonical signals |
A page must stay accessible but not appear in search | Use noindex; allow crawling |
URL patterns should not be crawled | Assess a targeted robots.txt rule |
A page is removed with no replacement | Return 404 or 410 |
An important page lacks internal links | Add relevant links |
Verify Technical SEO Fixes with Crawl Data
Using Google Search Console to Check Crawl and Indexing Signals
Use Crawl Stats to inspect Google’s crawl requests, response codes, host status and changes in crawling activity. Review the Page Indexing report for patterns affecting URLs, and use URL Inspection to investigate specific pages. Reports can take time to reflect changes, and an indexing status is not a complete explanation of why a page is or is not visible in search. Compare the evidence with your intended canonical URLs, internal links and response codes instead of treating one report as proof of the cause.
Comparing Googlebot Server Logs Before and After Remediation
Where log access is available, compare requests before and after the change. The group verified Googlebot requests by URL pattern and response code to see whether it continues to request unwanted variants or encounters redirect hops and errors. Check the period and site activity before concluding; publishing more pages or completing a migration can change request patterns. Server logs record what reached the server, while Search Console provides Google’s reporting, so use both views together when possible.
Measuring Outcomes Without Assuming Ranking Improvements
Record a baseline before making changes. Depending on the problem, this might include Googlebot requests to parameter URLs, the number of redirect hops, internal links to preferred URLs, or the discovery and indexing status of key pages. Re-run the crawl after implementation and inspect relevant URLs in Search Console. Track organic clicks, impressions and rankings separately over a suitable period. Improvements in crawling do not automatically create ranking gains, and changes in organic performance can have other causes. Report what the data shows, not what you hoped the fix would achieve.
Conclusion
Crawl budget optimisation starts with evidence, not blanket blocking rules. Identify the URL pattern, understand its purpose, apply the appropriate fix and monitor the results. If the cause is unclear or the issue affects a large site, a technical SEO audit can help prioritise the next steps. Explore Midland Marketing’s technical SEO services or SEO audit services for support.
Frequently Asked Questions
What is crawl budget optimisation?
It helps search engines focus crawling on useful URLs, particularly on large or frequently updated websites.
How can duplicate URLs affect crawl efficiency?
They can lead crawlers to request multiple versions of similar content, especially when many low-value URL variations exist.
How are orphan pages identified?
Compare crawl results with sitemap, CMS, analytics, Search Console and server-log data to find URLs without incoming internal links.
How should redirect chains be fixed?
Confirm the destination, shorten unnecessary paths, update internal links and sitemaps, and test for loops or errors.
When should robots.txt, noindex or canonical tags be used?
Use robots.txt to control crawling, noindex to exclude an accessible page from search, and canonical tags to signal a preferred duplicate URL.